Insights
Author, Not Approver: Redesigning the Human-in-the-Loop
Human-in-the-loop language collapses two different roles. Presence keeps regulators calm. Authorship is what customers actually experience. The redesign starts there.
Author, Not Approver: Redesigning the Human-in-the-Loop
The phrase human-in-the-loop is doing more work than it can hold. It is used to describe the reviewer who reads every model output and pushes back, the manager who signs a monthly narrative once and lets it regenerate on schedule, and the analyst who has not opened the document in six months but whose name still appears at the top of it. All three appear the same on the org chart. To the customer, the regulator, and the board, they are not the same at all. The redesign has to start where the language is failing: with the difference between presence and authorship.
Presence is what governance frameworks currently reward. A named reviewer, a documented sign-off, a screenshot of the approval workflow — those are the artifacts an audit expects, and they are what most companies produce. Authorship is a different thing. It is the specific human act of shaping the claim the company is about to make: choosing the framing, testing the assumption, deciding what the sentence has to mean before it goes out. When a workflow retains presence but loses authorship, nothing changes in the compliance file and everything changes in what the company is actually saying. This article is a working guide to seeing that gap and closing it.
What is the difference between presence and authorship in human-in-the-loop design?
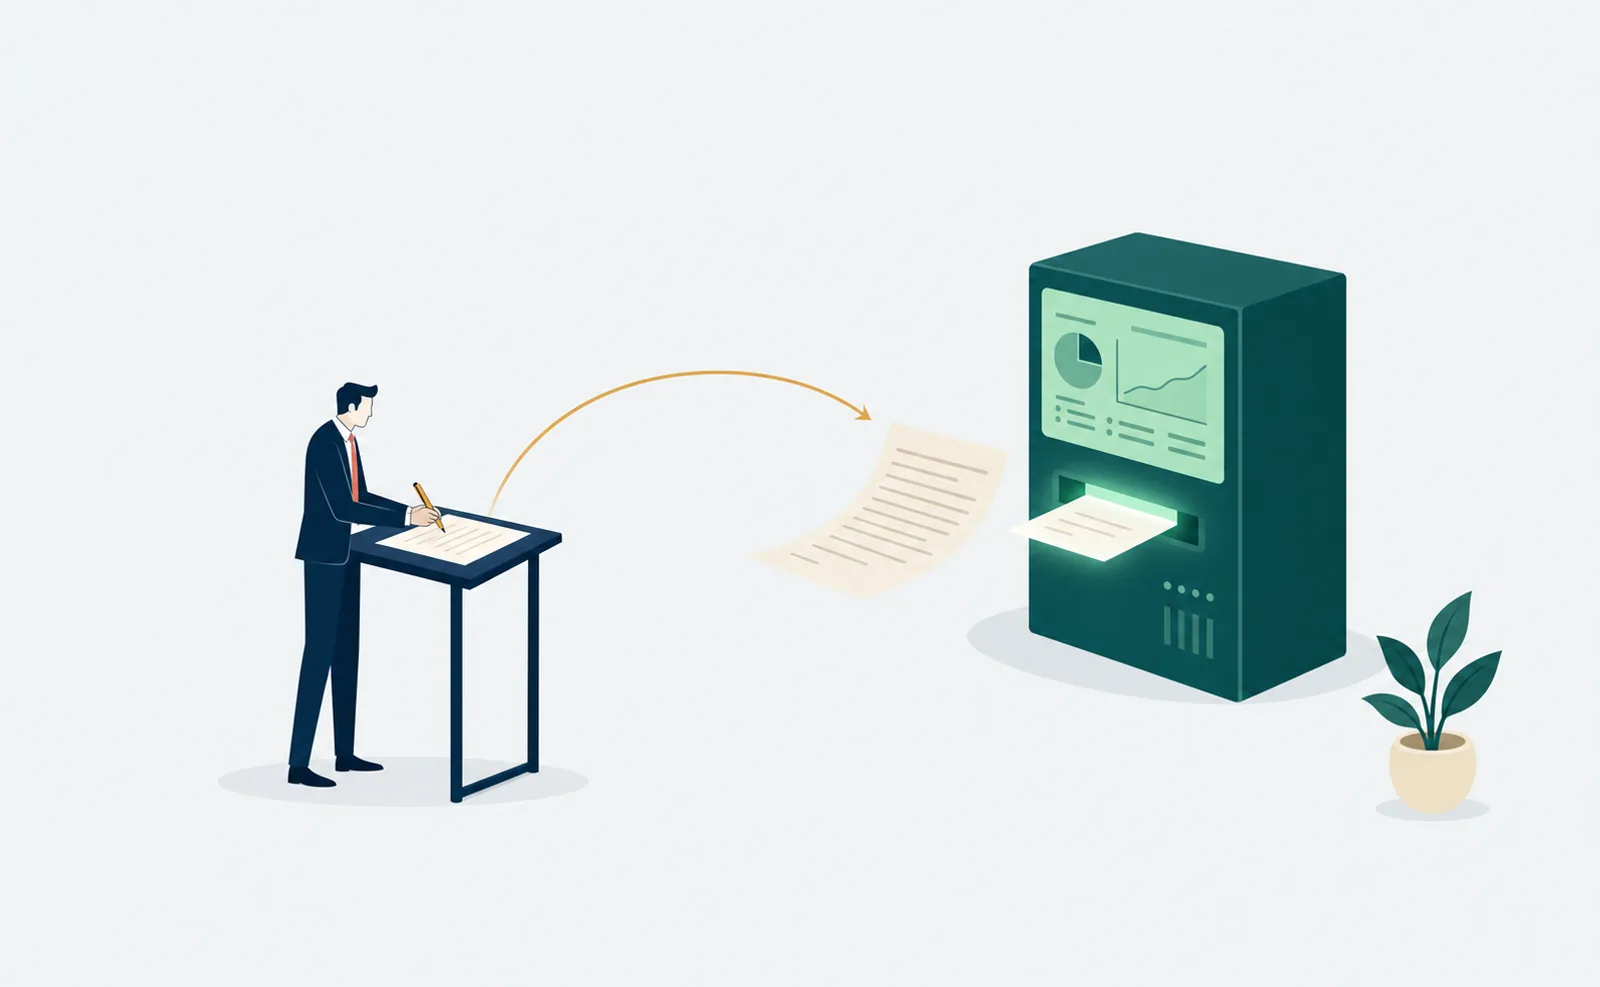
Presence is the fact of a human being in the workflow. Authorship is the fact of a human having shaped the specific claim the workflow produced. They used to be the same thing because a reviewer had to write, edit, or at least understand what they were approving. AI-augmented workflows have separated them. The model can now produce a defensible artifact — a variance narrative, a customer message, a hiring summary, a policy exception — that a reviewer can approve without ever having authored it. The signature is real. The authorship has quietly moved elsewhere, or nowhere.
The distinction matters because customers, regulators, and courts have never cared about presence. They care about what the company said and who is accountable for having said it. When something goes wrong, the question is not “was there a human in the loop” but “who wrote this.” Companies that cannot answer the second question have a governance problem their org chart hides.
Why does human-in-the-loop language keep failing?
Because it was designed for a world where reviewing was a smaller job than doing, and where the reviewer’s default posture was skepticism. In that world, “human review” was a meaningful safeguard because the review took nontrivial effort and the reviewer had cognitive skin in the game. AI-augmented workflows have inverted both conditions. The AI does the effort. The reviewer’s default posture drifts toward acceptance because the output is usually right and the volume is too high to inspect. What the policy calls review becomes, in practice, forwarding.
The failure is not that reviewers are lazy. It is that the role has been redefined by the technology without being redefined by the organization. The chart still says reviewer. The work has become clearance. Clearance is a legitimate function — it just is not the safeguard the chart implies. Treating one as the other is the source of most human-in-the-loop failures.
How does authorship redistribute itself when AI enters a workflow?
Silently, and usually toward the model. The first month, the reviewer edits every draft. The second month, the reviewer edits every third draft. By the sixth month, the reviewer edits when something looks unusual, and “unusual” has been redefined by what the model produces. The reviewer is still the named author. The actual authorship — the framing, the emphasis, the specific claim — has migrated into the training data, the prompt template, and the model’s stylistic defaults. No one authorized this migration. No one recorded it. It is visible only in the difference between what the reviewer would have written unaided and what the workflow now produces.
Some redistribution is fine. A finance controller does not need to author every line of a variance narrative from scratch; a customer-service lead does not need to compose every consolation message. The question is which claims still require a human author and which can safely become clearance work. That question has to be answered claim by claim, not workflow by workflow. It cannot be answered at all if the org chart treats reviewer and author as the same word.
What does redesigning the human-in-the-loop actually look like?
It looks like naming, per workflow, which specific claims require authorship and which require only clearance — and then designing the role and the metrics to match. An authorship seat is measured on the quality of the claim: did the human shape the framing, test the assumption, decide the emphasis. A clearance seat is measured on throughput and exception detection: did the human catch the small percentage of outputs that fell outside the model’s competent range. Both are legitimate. Neither is the other.
Concretely, the redesign has four moves. First, inventory the workflows that produce claims the company is willing to be held accountable for. Second, for each of those workflows, decide which specific outputs require authorship and which can be cleared. Third, staff the authorship seats with people whose calendars, incentives, and job descriptions actually support the shaping work — not people who inherited the role because the workflow used to require them and no one has renamed it. Fourth, build the clearance seats honestly: give them the volume they can inspect, the exception rules they need, and the authority to escalate without penalty. The compliance file will look the same. The company will not.
What is a Second Map of Work, and where does authorship live on it?
The org chart is the first map of work. It shows reporting lines, sponsors, and formal accountability. It does not show where a person’s cognitive shaping actually enters the output. A Second Map traces the flow of authorship through the workflow: at which point does a human touch this claim in a way that changes what the company says. The Second Map is often shorter than leaders expect. Many workflows that appear to have five human touchpoints have only one authorship point, and it may not be the one the org chart implies.
Drawing this map is unglamorous work. It usually involves sitting with the workflow owner and the actual doer and asking, at each step, “what would change in the output if you were not here.” Where the honest answer is “nothing meaningful, the model would still produce a defensible artifact,” the human is doing clearance. Where the honest answer is “the framing would be different, or the assumption would go unchecked,” the human is doing authorship. The Second Map lets a leadership team see the redistribution that has already happened and decide whether to accept it, redesign it, or reverse it.
A short example
Consider a mid-market retailer whose finance function reviews an AI-drafted margin narrative every quarter. Two years ago, the controller wrote the narrative from the raw data, argued with the CFO about the framing, and rewrote paragraphs the night before the board pack went out. Today, the model drafts the narrative from the operating signals, applies the house voice, and produces a document the controller reads once and signs. The compliance file is identical. The workflow diagram is identical. The chart still shows the controller as the reviewer.
What has changed is that no one is now testing whether the framing is honest. The model chose the emphasis based on last quarter’s structure. The controller, whose calendar has been reallocated to exception work, accepts the emphasis because the numbers reconcile. The board reads a narrative the company has not authored in any meaningful sense. Nothing has failed yet. Something will, and the accountability trail will lead to a controller who did not write the sentence the board relied on. The redesign is not more review. The redesign is naming that the controller’s authorship seat has quietly become a clearance seat, and deciding whether that is what the company actually wants.
Frequently asked questions
Is a human-in-the-loop enough to satisfy AI governance requirements? For a growing number of regulators, no. The direction of travel — in the EU, in financial-services supervision, and in emerging state-level rules in the U.S. — is toward asking who authored the specific output, not whether a human was present in the workflow. Companies that can point only to presence, not authorship, are increasingly exposed on both regulatory and reputational grounds.
How is authorship different from accountability? Accountability is who answers for the outcome. Authorship is who shaped the specific claim that produced the outcome. They should line up but often do not. A leader can be accountable for a decision whose framing was authored entirely by a model and cleared without pushback. Aligning the two is the substantive work of AI governance.
Can a clearance seat safely replace an authorship seat? Sometimes. For routine, low-consequence outputs, clearance is appropriate and efficient. The mistake is doing the substitution silently, workflow by workflow, without deciding whether the specific output category needs a human author. Explicit substitution is a design choice. Silent substitution is drift.
How do you identify workflows where authorship has already migrated to the model? Ask the named reviewer what would change in the output if they were not there. If the honest answer is “very little, the model would produce a defensible version,” authorship has migrated. The output may still be fine. The company should know that it now owns a model-authored claim and decide whether that is acceptable for the specific decision it feeds.
Jose J. Ruiz is CEO and Managing Partner of Alder Koten and Chairman of Anker Bioss. He develops these ideas at book length in AI in the Org Chart: A Leadership Guide to Implementing AI Without Losing Human Judgment, Accountability, and Trust, published by Elavant Press and available on Amazon.
If your organization is redesigning executive roles around AI-augmented workflows — or trying to see where authorship has already migrated — start a conversation with our practice.