Insights
The Right to Pause: Why AI Review Needs a Protected Way to Say No
Human review of AI decisions fails quietly when every pause is measured as delay. How metrics and service targets penalize judgment, and how leaders can protect the reviewer's right to stop.
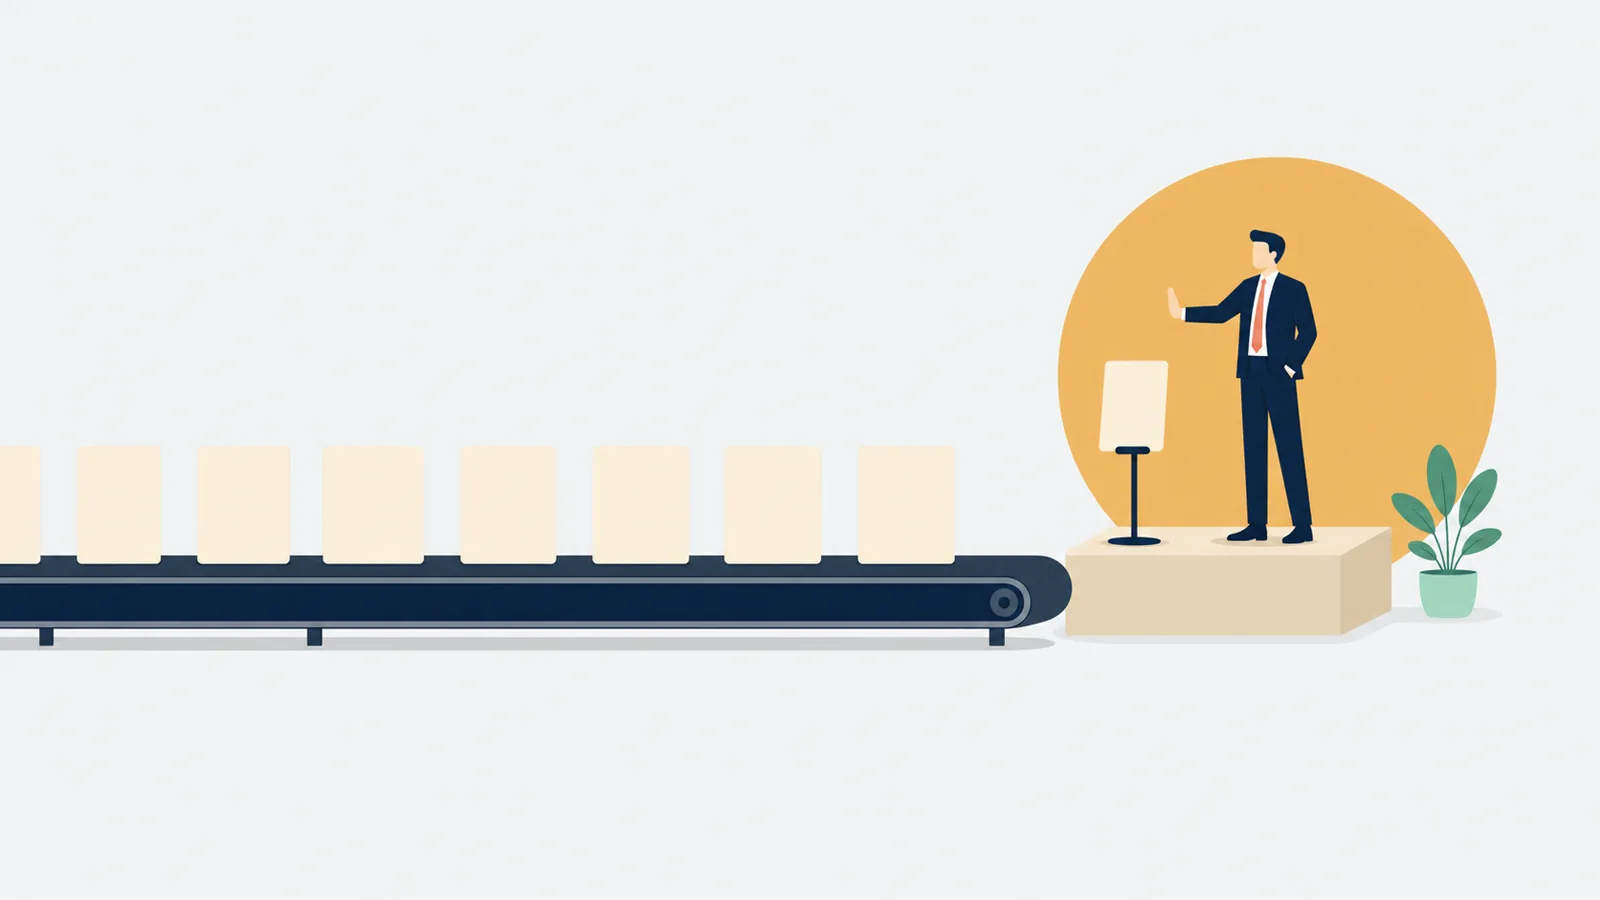
Human review of AI decisions usually fails without anyone refusing to do it. The reviewer has every button she needs (approve, deny, request information, escalate), but the workflow measures every pause as delay, so the one thing she cannot easily do is stop and say, “this case cannot be decided from the summary.”
That is a design problem, not a character flaw, and it is mostly settled before the reviewer opens the case. What follows looks at why a human checkpoint can look safe on a dashboard and still contain no real room to judge, how ordinary operating metrics quietly teach people that challenge is expensive, and what operations and people leaders can change so that a responsible pause reads as judgment rather than variance.
Why does human review of AI decisions fail even when a person is in the loop?
Many organizations add a human review step for the right reason: to keep a person involved where consequence matters. The policy says a human makes the final decision. The record shows review. The dashboard shows approval.
The real test is not whether the reviewer is involved. It is whether she can refuse the system’s momentum without becoming the problem. A review step can give a person a role without giving her discretion, responsibility without authority, or context without time. Any one of those gaps turns review into ritual, and from a distance the ritual looks exactly like oversight.
AI makes these gaps harder to see. A generated recommendation can make a case look settled before the reviewer has entered it. A clean score, a short summary and a drafted rationale all arrive at once, and the easiest path is to keep the work moving.
What does a reviewer’s pause actually cost her?
Consider a composite case. A benefits reviewer at a large employer has a case open. The model’s score sits near the top of the screen, confident. The recommendation is already written. The summary is short enough to trust quickly and complete enough to discourage hesitation. One note in the underlying file does not fit the rationale: a detail about the employee’s situation that seems to matter more than the score suggests.
Outside the case, the clock is running. The team has a service target. The queue has aged items. Her supervisor can see how long the file has been open. Handling time is the headline metric in her performance review.
She can approve and stay in the rhythm. She can escalate, but escalation is slow and draws attention. She can override, but the override box asks for a reason before she has finished finding the words. She can ask for more information, though the answer may come back in the same structured form that produced her doubt. Whatever she chooses, the dashboard will register the delay. It will not register the reason.
Nothing here requires bad intent. The tool may be useful, the policy reasonable, the manager responsible. As one passage in a recent book puts it, “The workflow does not have to say, ‘Do not challenge the recommendation.’ It only has to make challenge expensive.”
How do metrics and service targets quietly penalize judgment?
People become fluent in the real rule long before anyone writes it down. They learn it from the signals around the work. The first time a reviewer slows a case for the right reason, the message travels faster than the case. Her manager can ask what she saw, or ask why the queue stalled. The team hears the difference.
The usual operating instruments all push in one direction:
Handling time treats every minute spent testing a recommendation as cost, with no way to distinguish a responsible pause from inefficiency.
Override rates are often read as variance from the model, a sign the reviewer is out of calibration, rather than as evidence of judgment.
Queue dashboards make delay visible to supervisors in real time while making the reason for it invisible.
Performance reviews reward consistency and throughput, which are exactly the qualities a reviewer loses when she stops to think.
Over time the reviewer stops testing the boundary. She stops asking for the missing fact. She stops treating discomfort as information. She becomes faster, more consistent and easier to manage. The process improves on the dashboard while the person thins inside the work. The organization never asked her to abdicate judgment. It taught her that judgment costs too much.
What is the Space of Autonomy in AI-assisted review?
The reviewer does not need unlimited freedom, and serious work cannot run on personal bravery. She needs a bounded place to stand.
That bounded place is the Space of Autonomy: the lived zone between what has been delegated to a role and what must be escalated beyond it. The Border of Delegation defines what she is trusted to decide, adapt and carry. The Border of Escalation defines when risk, ambiguity or consequence exceeds her remit and must move to a role with a wider one. Between those borders sits the space where judgment can happen.
In AI-assisted review, that space is concrete. It is what she can see beyond the summary, whether the underlying file or only the score. It is what she can question without leaving the screen. It is what happens to her queue time when she hesitates, and who reads that number at the end of the week. It is whether the last person who paused was thanked or timed.
The size of the space should fit the consequence of the work. Routine, low-consequence decisions can be automated or lightly reviewed. Where a decision affects employment, care, safety, access, legal standing or a promise made in the company’s name, the reviewer needs more than a final click. Without that, the organization has not designed human judgment into the process. It has put a human surface on it.
How can leaders protect the right to pause?
Most of the work belongs to managers and to the people who design operating metrics.
Define where the pause is expected. Name the case types and signals (a note that contradicts the rationale, a missing fact, a situation outside the model’s pattern) where reviewers are expected to stop. A pause in those conditions is part of the job, not an exception to it.
Measure pauses separately from delay. Track responsible holds as their own category, with a short reason, and exclude them from handling-time targets. Review them for quality, not volume.
Read overrides as information. Treat a cluster of overrides as a signal about the model, the policy or the data, not as a calibration problem with the reviewer. Ask what they saw before asking why the number moved.
Make “cannot decide from the summary” a real option. Give reviewers a way to route a case for fuller review that does not require them to argue against the recommendation in a text box first.
Coach the boundary in ordinary moments. Whether a reviewer can say no is mostly decided by how her manager reacts to the first responsible delay, the first override and the first person who notices what the system missed. Thank the pause publicly when it was right. Coach it privately when it was not.
Protect the reviewer when the pause creates friction. A responsible stop will sometimes miss a service target. Managers have to absorb that cost visibly, or the team will learn the opposite lesson.
Frequently asked questions
What is the right to pause in AI decision review? It is a protected, legitimate way for a human reviewer to stop an AI-assisted decision when the case cannot be decided from the system’s summary. It includes time, access to the underlying facts, authority to hold or route the case, and assurance that a responsible pause will be treated as judgment, not measured as delay.
Why do human reviewers rubber-stamp AI recommendations? Usually because the workflow makes challenge expensive, not because reviewers are careless. Handling-time targets, visible queue dashboards, override rates read as variance and performance reviews that reward throughput all teach people that approving keeps them safe. Over time, reviewers learn to stop raising doubts the system is not designed to hear.
How should you measure human reviewers of AI decisions? Separate responsible pauses from delay, and review them for quality rather than count. Track whether overrides and holds were well-founded, what they revealed about the model or policy, and how quickly cases reached the right decision-maker. Measuring only speed and agreement with the model rewards the absence of judgment.
What makes human-in-the-loop oversight meaningful? A reviewer who can see beyond the score, has time proportional to the consequence, holds clear authority to stop or escalate, and works for a manager who treats a responsible pause as part of the job. Without those conditions, a human checkpoint records that someone was present but not that anyone judged.
Operations and people leaders redesigning how AI-assisted review is measured and managed can start a conversation. Anker Bioss advises organizations on governing judgment in AI-shaped work. Related reading: The Autonomy Paradox for Flow and Performance and Approval Is Not Judgment: Decision Records for AI-Assisted Work.
Jose J. Ruiz is CEO and Managing Partner of Alder Koten and Chairman of Anker Bioss. He develops these ideas at book length in AI in the Org Chart: A Leadership Guide to Implementing AI Without Losing Human Judgment, Accountability, and Trust, published by Elavant Press and available on Amazon.